Data Warehouse · Big Data · Data Engineering

Jiaxin Zhang

Resume Snapshot

Data Engineering & Data Warehouse Profile

  • Profile Second bachelor's degree in Data Science and Big Data Technology from China Agricultural University; targeting Data Engineer and Data Warehouse Engineer roles
  • Production 10 months of enterprise data warehouse experience at Muyuan's headquarters, working with MaxCompute, DataWorks, Hologres, and SQL
  • Warehouse Dimensional modeling, layered transformations, dependency governance, data-quality validation, and incident tracing
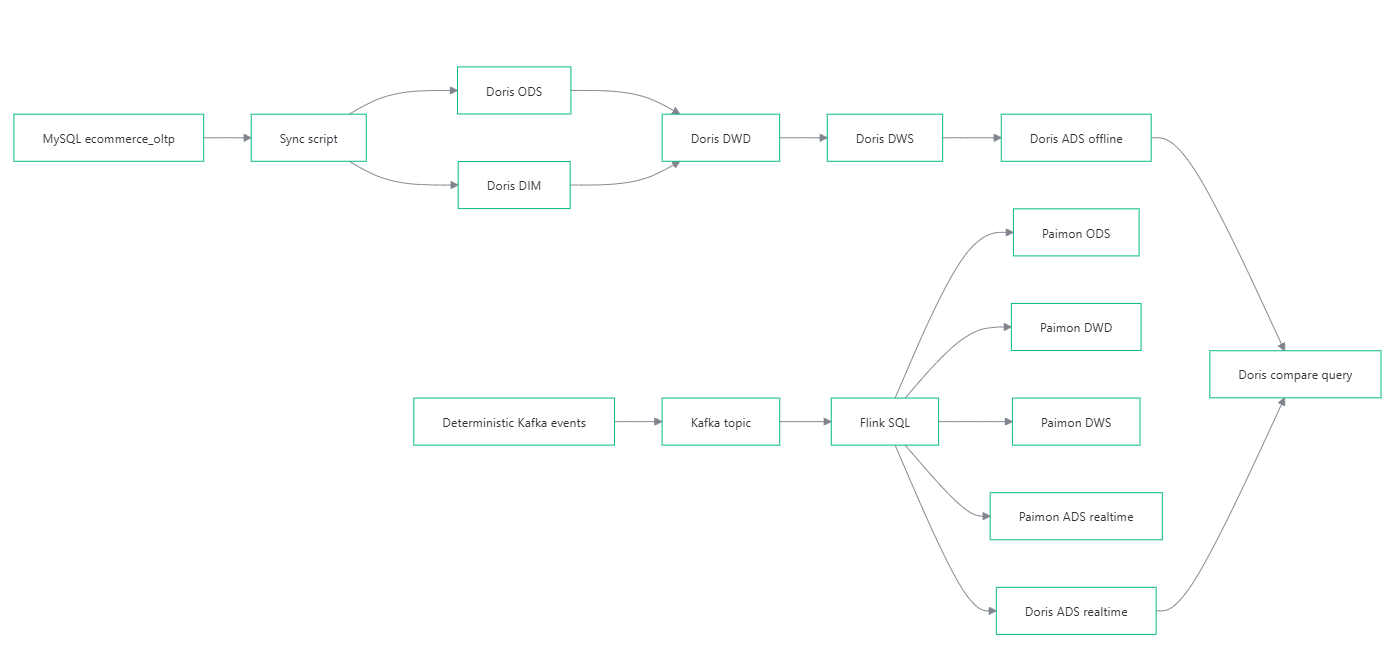
  • Streaming Reproducible hands-on work with Flink SQL, Kafka, Paimon, Doris, and batch-versus-streaming metric reconciliation
  • AI Data Governed Novel synthetic-data pipeline and Mini-C4 web-corpus preparation pipeline

Selected Projects: Engineering Evidence, Not Just Claims

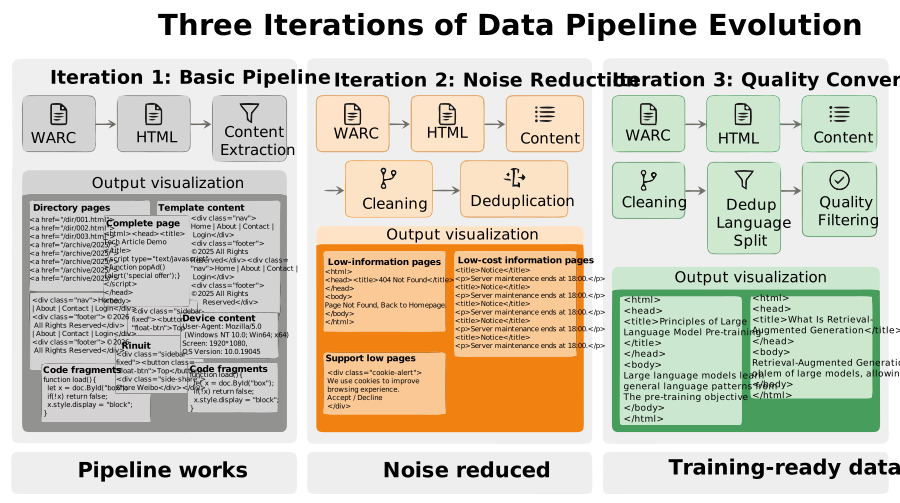
LLM Data Mini-C4 Validation
Three iterations of the Mini-C4 data pipeline

Mini-C4 Web Corpus Pipeline

Reproduces and extends the open-source Mini-C4 workflow on a single CPU / WSL machine: WARC parsing, main-text extraction, cleaning, deduplication, language routing, quality filtering, training packaging, and consistency checks.

10Pipeline stages orchestrated
14/14Consistency checks passed
View project details ->
Production Case DataWorks Lineage Review Scheduling Governance

Production Case: Governing a Twice-Daily Dependency Chain

Restructuring a mixed-frequency schedule

For a chain combining self-dependencies, cross-day dependencies, and mixed schedules, I mapped lineage and configuration first, split the change surface by core, transformation, and cache layers, then validated row counts, business metrics, and historical backfills.

01 Classify dependencies Label weekly, daily, and hourly cycles plus normal, self, and cross-day dependencies.
02 Separate risk layers Distinguish core tables, transformation tables, and cache layers to control the blast radius.
03 Isolate time windows Separate early-morning and afternoon runs while aligning cross-day boundaries.
04 Validate three ways Cross-check volume, business metrics, and historical backfill results.

Delivery scope and incident handling

  • ScopeAdjusted upstream tables and dependent chains for twice-daily delivery.
  • PipelineChanged ODS extraction frequency and intermediate transformations, validating each upstream/downstream layer.
  • IncidentLocated and fixed a case-sensitivity mismatch in transferred-group data.

Technical Capability Map

01

Cloud Warehouse

Production cloud warehousing and orchestration

  • MaxCompute
  • DataWorks
  • Hologres / SQL
02

Model & Quality

Layered modeling and data-quality governance

  • ODS / DWD / DWS / DM
  • Dimensional modeling
  • Quality validation / incident tracing
03

Realtime Practice

Reproducible streaming practice

  • Flink SQL / Kafka
  • Paimon / Doris
  • Metric contracts / dual-path reconciliation
04

Engineering

Reproducible engineering delivery

  • Python / Pandas
  • Docker / WSL2
  • Testing / documentation / lineage

Credentials & Public Evidence

Certifications establish a knowledge baseline; merged open-source work and public material add independently verifiable evidence of collaboration and business communication.

Professional Certifications

Professional certifications relevant to target roles

Certifications support the profile; public repositories, run records, and validation results remain the primary engineering evidence.

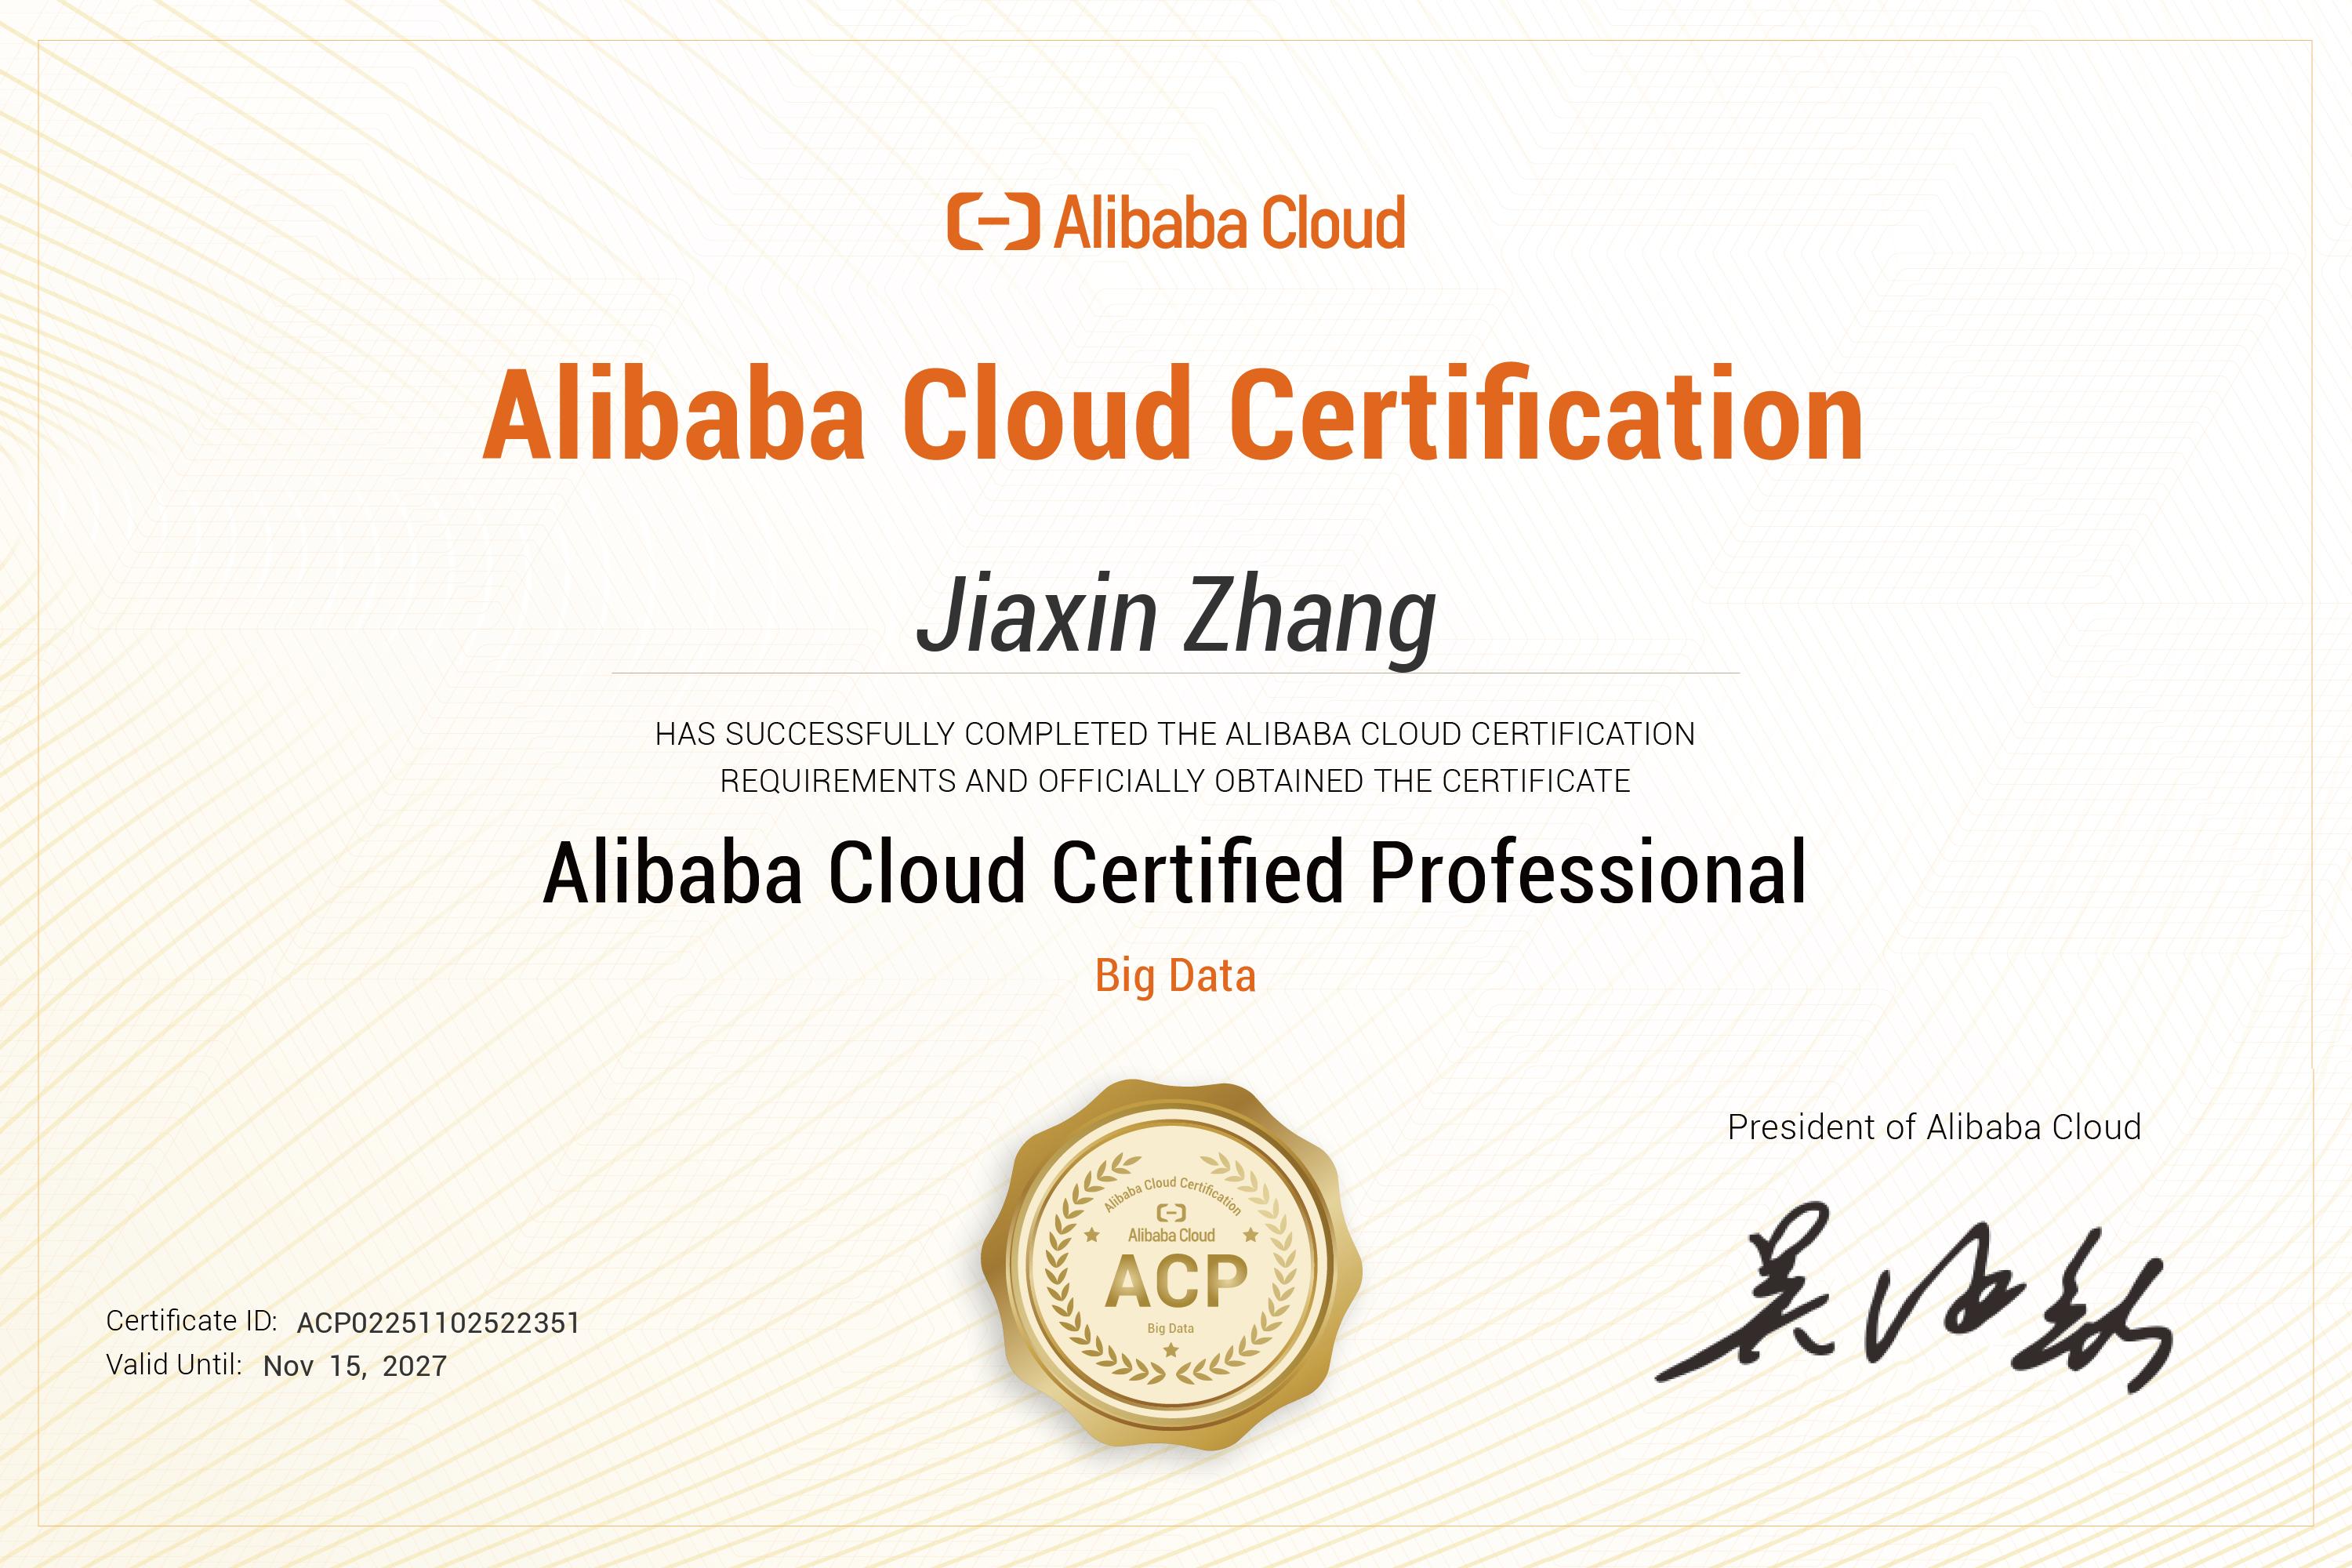
Jiaxin Zhang's Alibaba Cloud ACP Big Data certification
Alibaba Cloud ACP · Big Data

Alibaba Cloud Certified Professional — Big Data

Knowledge credential supporting hands-on cloud warehouse experience and portfolio evidence.

Valid through Nov 15, 2027 View original certificate ->
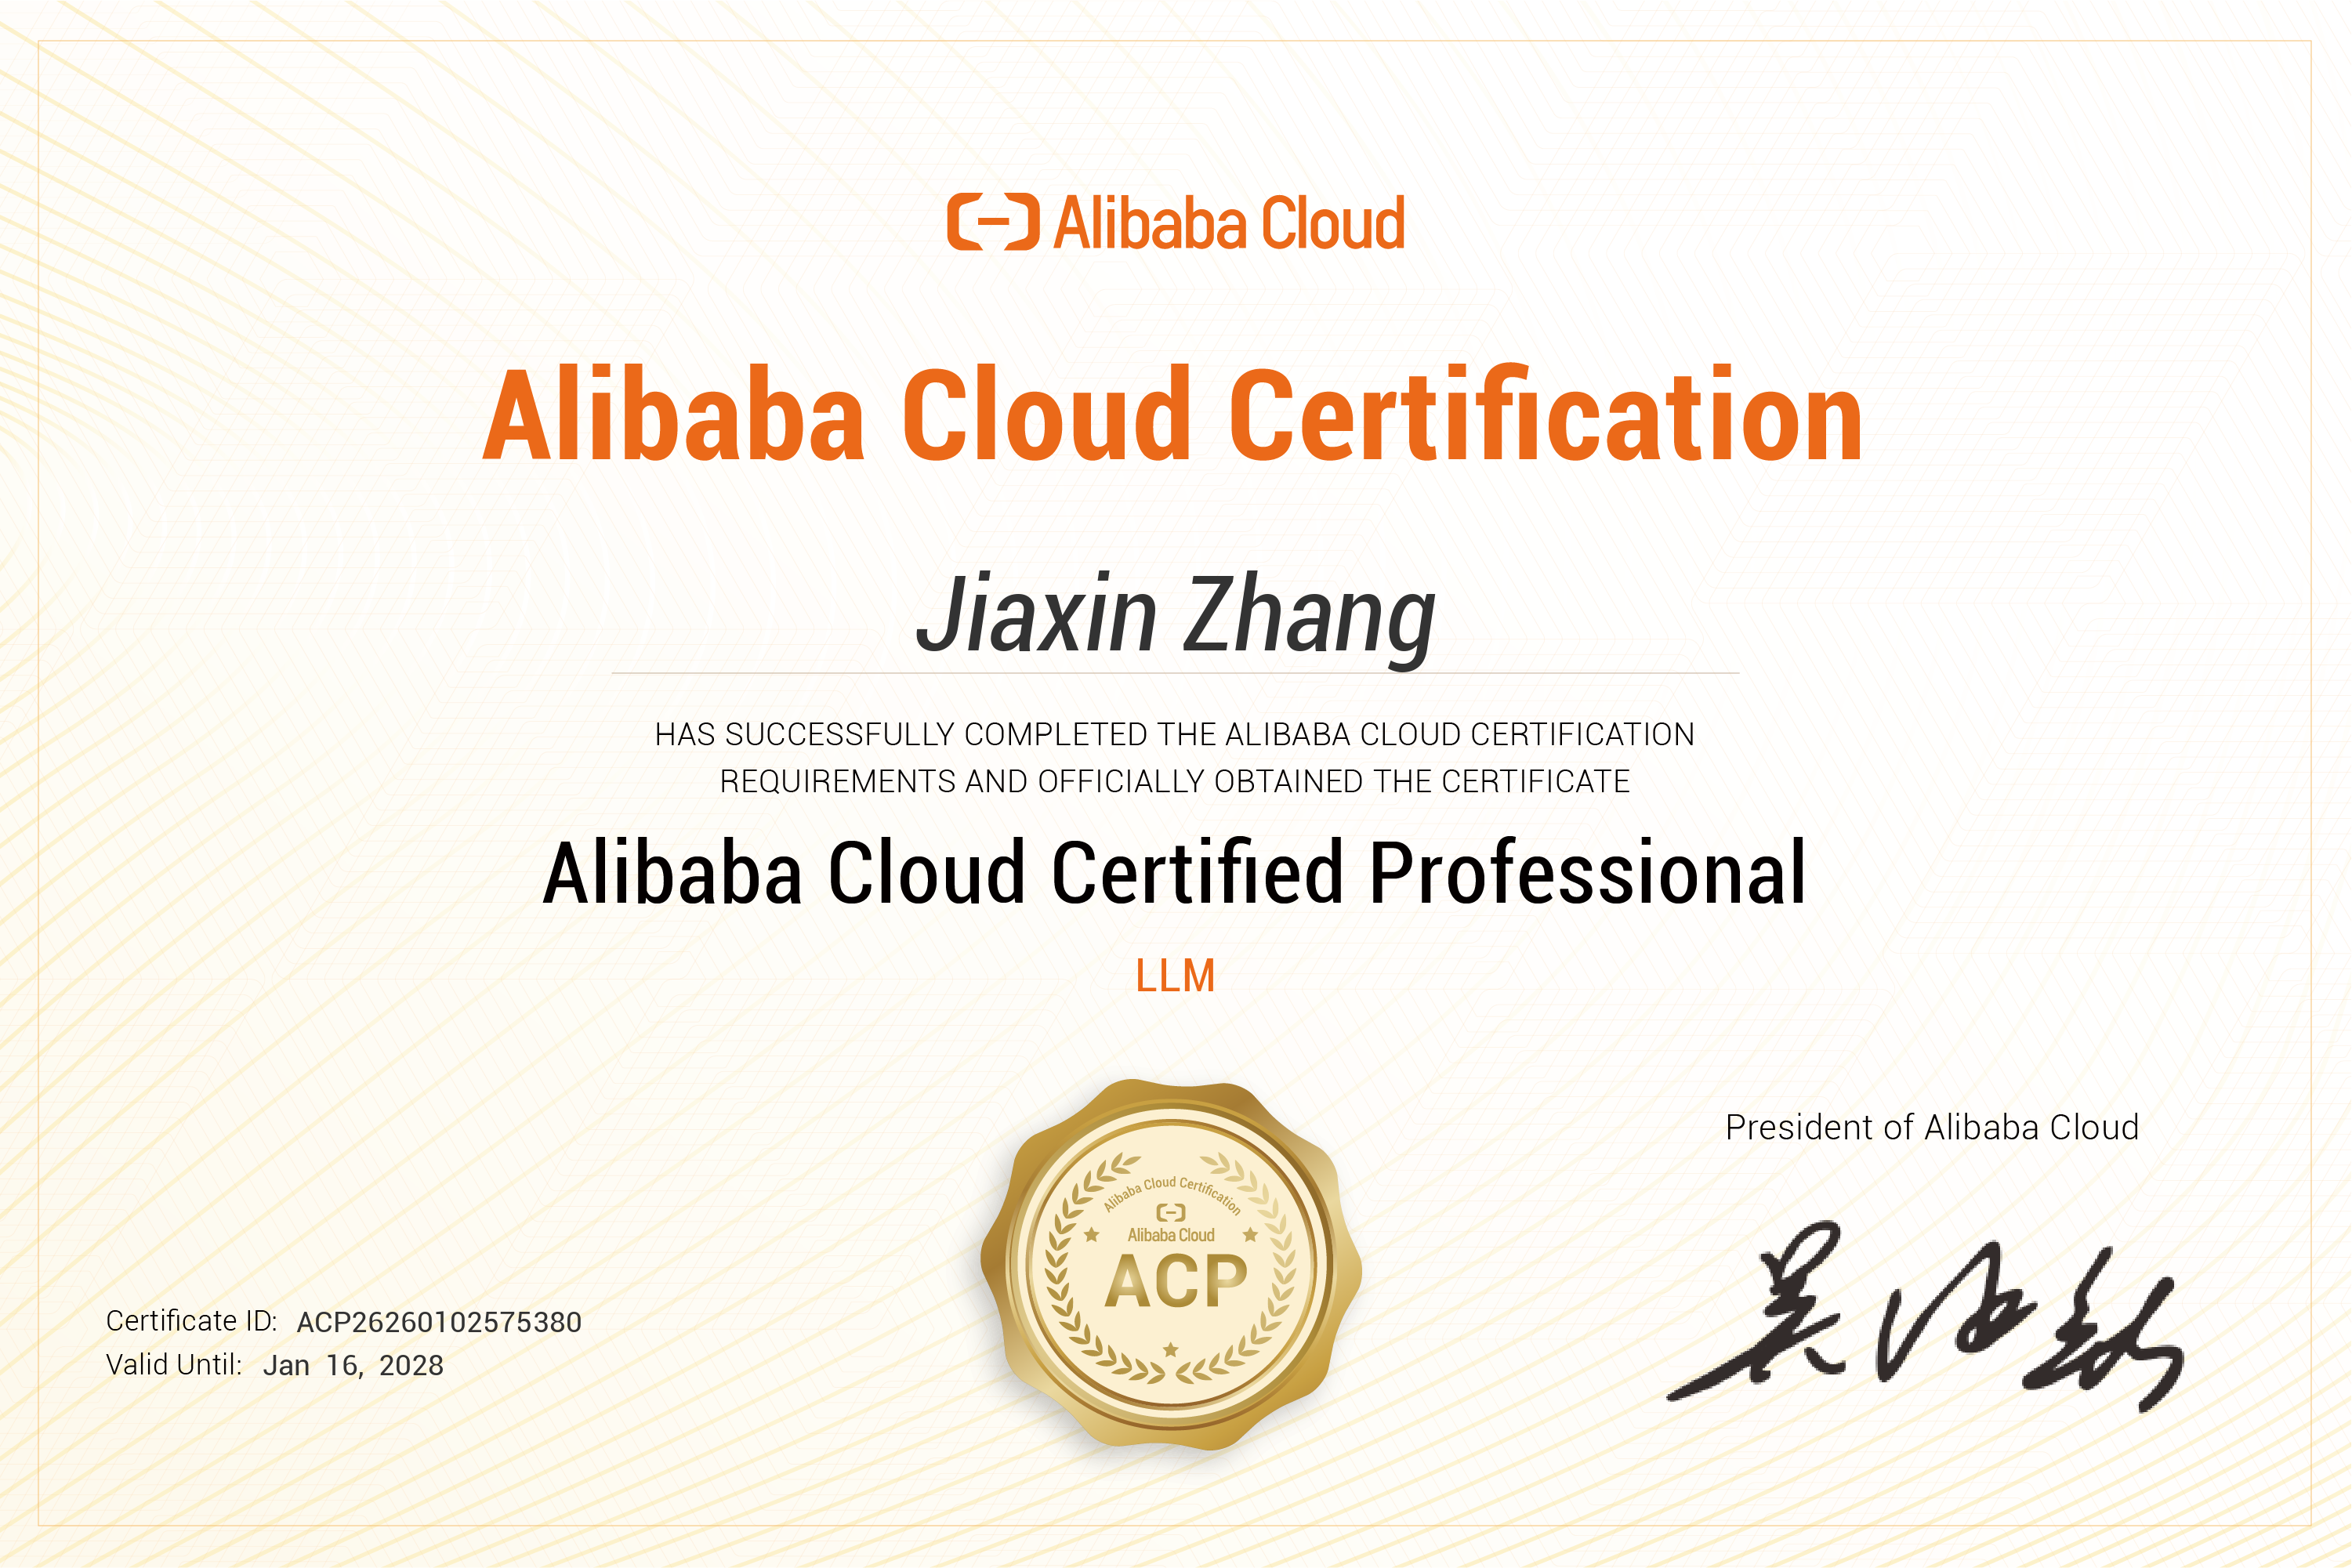
Jiaxin Zhang's Alibaba Cloud ACP Large Language Model certification
Alibaba Cloud ACP · LLM

Alibaba Cloud Certified Professional — Large Language Model

Supports the LLM foundation represented by the Mini-C4 and pre-training data-governance projects.

Valid through Jan 16, 2028 View original certificate ->

Technical Writing: From Incident Diagnosis to Durable Practice

Two public write-ups cover real-time pipeline troubleshooting and file-based state management for AI tools, with explicit boundaries, validation methods, and reusable conclusions.

Alibaba Cloud Flink CDC × DataHub: A Closed-loop Troubleshooting Guide

Reviews six synchronization and consumption failures by separating control plane, data plane, event semantics, and validation signals into a reusable diagnostic sequence.

Read on GitHub ->

File-based Memory for OpenClaw and Codex

Stores task state, incident logs, shared knowledge, and permission boundaries in portable files so the same operating method can be reused across OpenClaw and Codex.

Read Chinese-language article ->

Contact

Open to data engineering and data warehouse opportunities where reliable pipelines create measurable business value.